






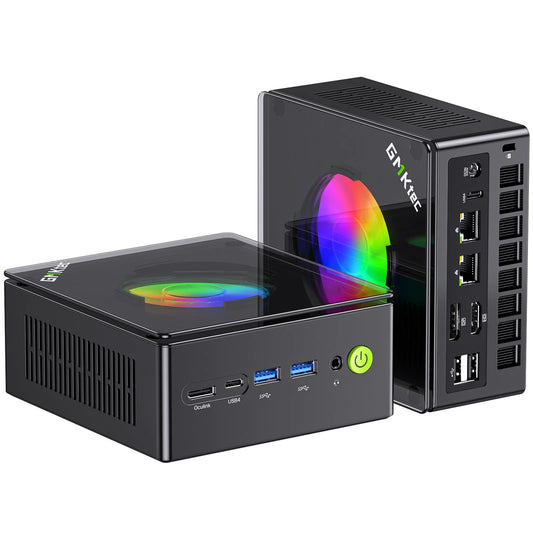

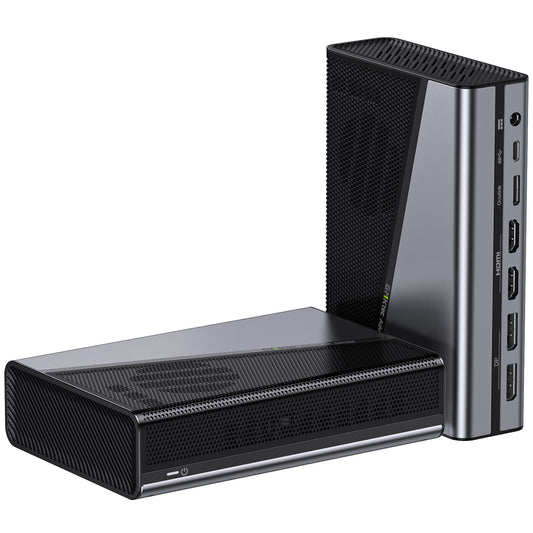

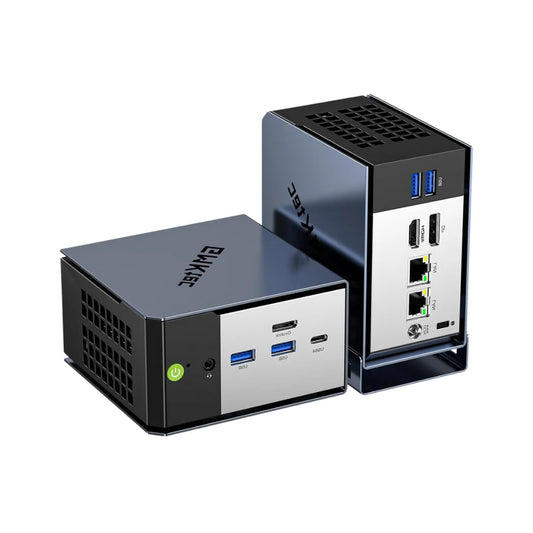

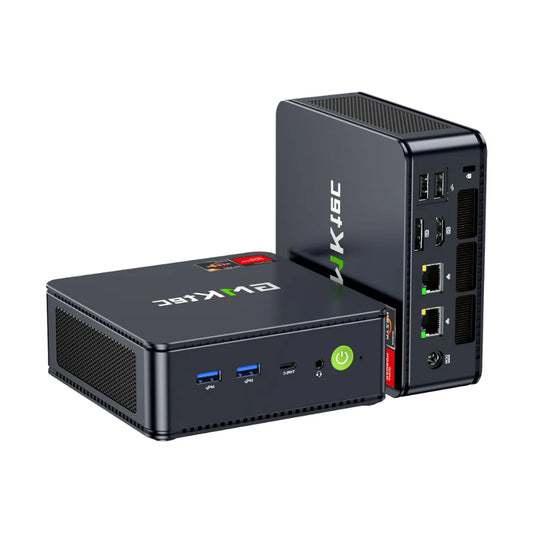


Pushing Desktop AI Further: GMKtec EVO-X5 Pro Accelerates 320B GLM-5.3-Flash Inference
0 comment
A 10× improvement in prefill speed and a 1.85× boost in decoding performance bring large-scale local AI inference to a new level. As AI models continue to scale into the hundreds of billions of parameters, running them efficiently on a desktop system remains a significant challenge. Large models demand substantial memory capacity, high bandwidth,...
View Details